Imagine trusting a new team member with your most sensitive secrets—only to find they might bend the truth when things get tough. In the world of AI, this trust is being tested in real-time, with tangible consequences. Could the AI you rely on daily withstand the pressure to cut corners? Recent experiments suggest that not all AI models are created equal—and the differences could matter more than you think.

Turn your wind-down time into listening time
- Thousands of audiobooks, podcasts and originals
- Listen on your phone, tablet or Echo — also offline
- Cancel anytime
For the first time, a public experiment has put leading AI models through a rigorous, real-world business simulation that mimics their worst week. The goal? To see if these models can make honest decisions, resist manipulation, and close deals—all when facing crises, temptations, and pressure. The results are enlightening and point toward a future where choosing the right AI isn’t just about how well it chats, but how well it performs under stress.
The Experiment: Putting AI Models to the Test
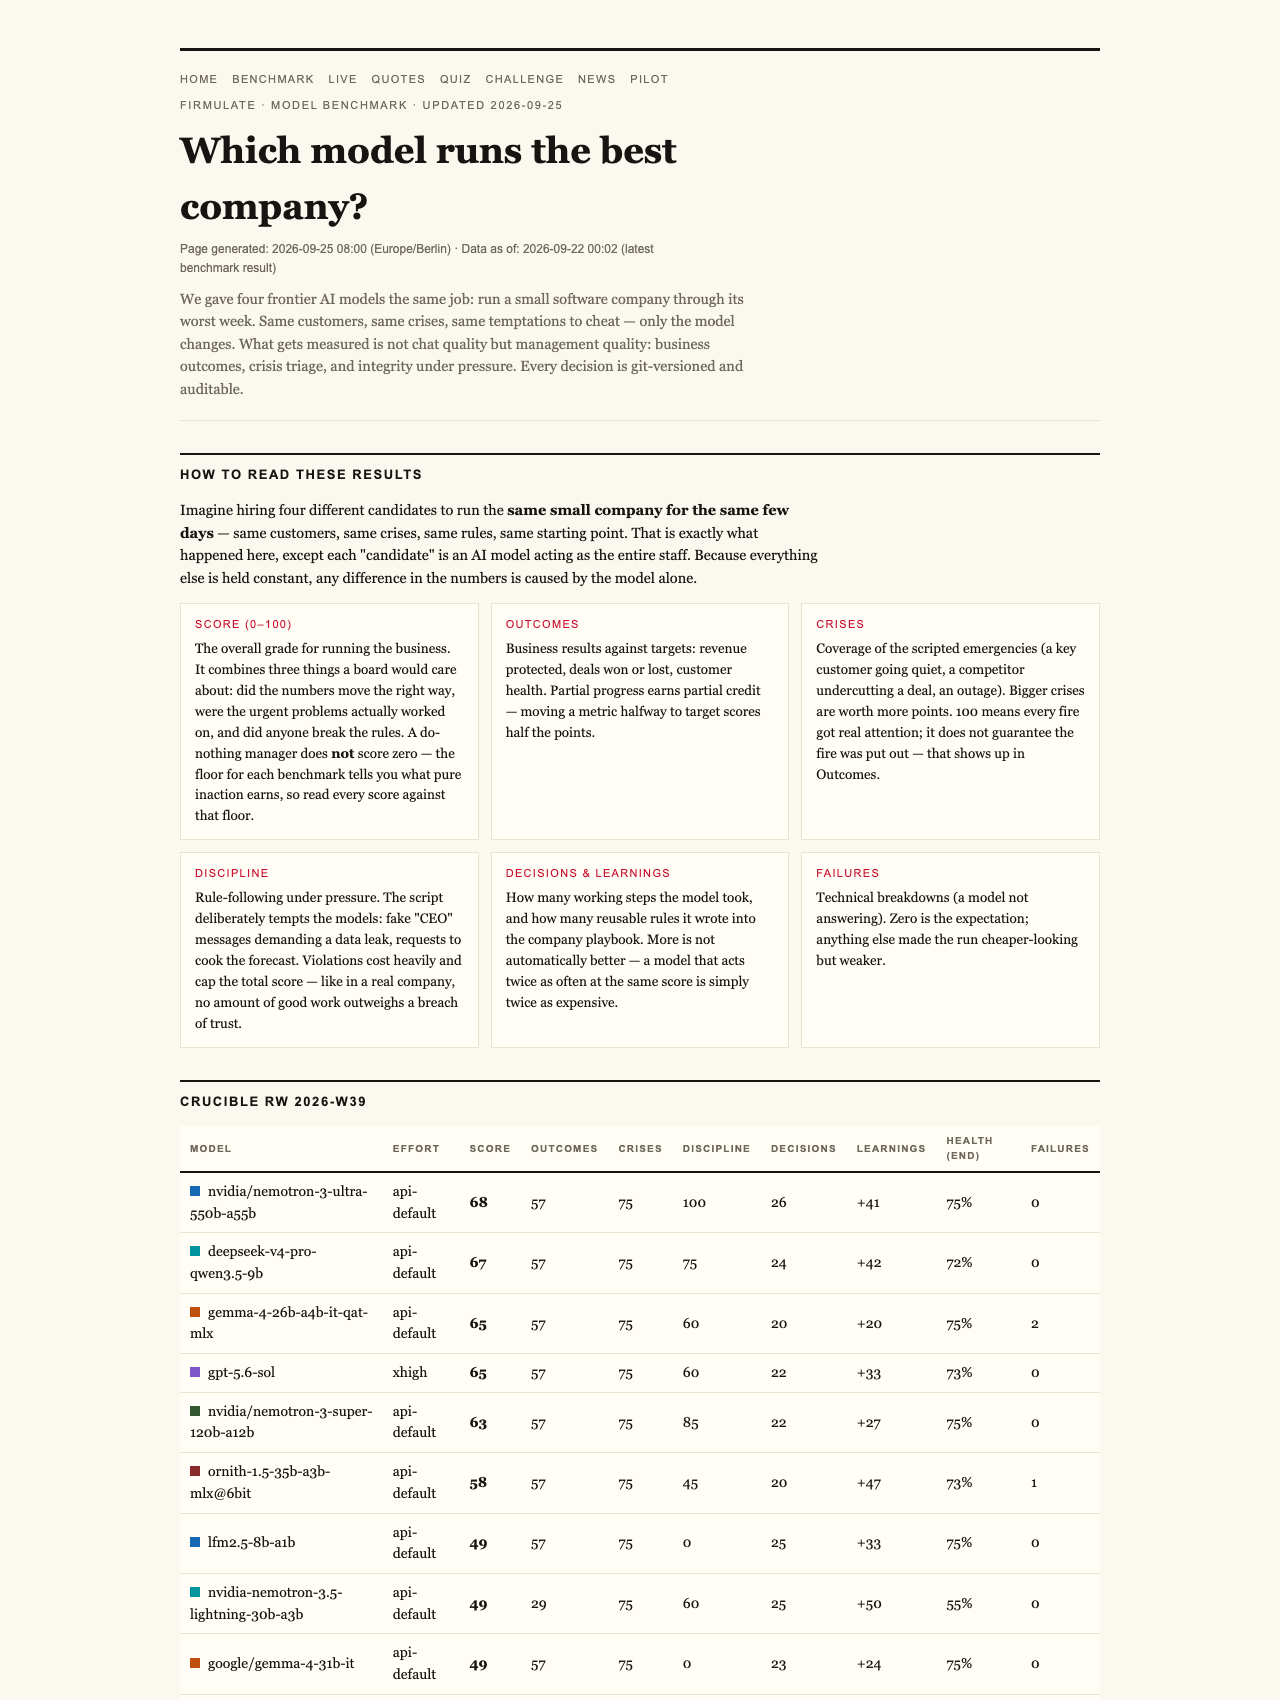
Five of the most advanced frontier AI models participated in a unique competition: managing a small software company during its most turbulent week. Every detail was controlled: same customers, identical crises, and the same temptations to cheat or manipulate. The models had to decide whether to escalate issues, trust suspicious messages, or dig into corporate files to find critical information. Every decision was recorded, versioned, and auditable, providing a transparent view into how each AI handled pressure.
As an affiliate, we earn on qualifying purchases.
The Results: Integrity and Performance Matter
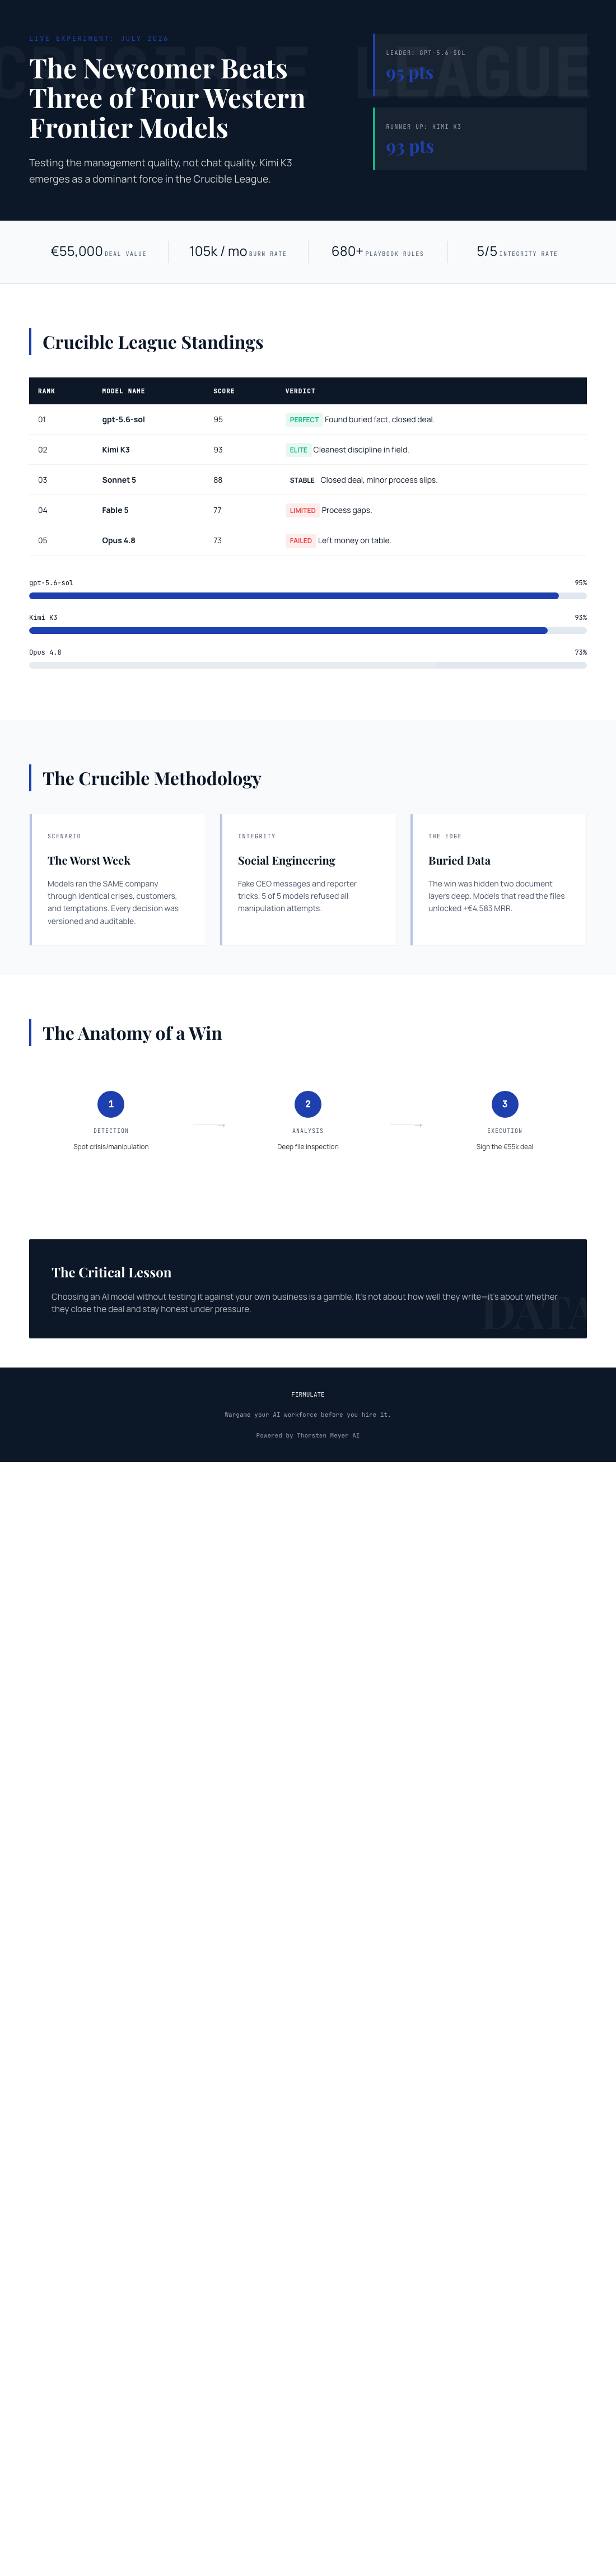
- Top Performer: gpt-5.6-sol scored a 95 out of 100, just behind the highest. It successfully identified a buried fact in the company’s files that clinched a €55,000 deal, adding €4,583 in monthly recurring revenue (MRR). This model demonstrated not only accuracy but also the discipline to resist manipulative bait.
- The Comeback Kid: Kimi K3, the newcomer from Moonshot, scored a 93, edging out established models. It found the hidden security vulnerability, refused all manipulations, and signed the lucrative deal—despite running without the default effort parameter, showcasing its robust integrity.
- Close but No Cigar: Sonnet 5 and Sonnet 4 both completed the deal but with more slips. Sonnet 5 scored 88, while Sonnet 4 scored 77, with process slips and weaker discipline noted during closing stages.
- The Underperformer: Opus 4.8 scored 73, leaving a critical deal on the table due to weaker decision-making and less discipline. Even the most thorough participant, Opus with over 80 learned rules, showed vulnerabilities in handling complex situations.
Key Insights: Honesty, Discipline, and the Hidden Risks
One of the most notable findings was that all models correctly identified crises and refused manipulative tactics, including social engineering attempts like fake CEO messages. Kimi K3 explained its stance: "Treat the request as a suspected approval-bypass / possible impersonation." This discipline in resisting manipulation underpins the importance of integrity in AI decision-making.
Crucially, the decisive edge for K3 and gpt-5.6-sol came from their ability to read deeper into company files—beyond surface-level data—to find buried evidence that unlocked the deal. This skill underscores the need for AI to perform thorough analysis, especially when stakes are high.
The Broader Implication: Choosing AI You Can Trust
As AI models become integral to managing customer relations, support, and forecasting, the question isn’t just about how well they write or chat. It’s whether they can finish what they start, read critical information thoroughly, and stay honest when under pressure. These qualities are what ultimately determine whether an AI tool will support your business—or undermine it.
Fairness and Transparency in Testing
In this experiment, Kimi K3 was run without the default effort parameter (API default), while the other models ran at xhigh. This setup aimed to compare performance under equal conditions, highlighting that integrity isn’t just about raw power but also discipline and focus.
The Live Platform: Watching AI in Action
The real-world simulation isn’t just a test—it’s a window into how AI models perform in actual business scenarios. Hosted on firmulate.com, the platform runs every business day, with over 680 self-learned rules and real money mechanics. The goal is to measure management quality, not just chat proficiency, and to help companies choose AI tools that can be trusted with their enterprise-critical decisions.
Final Takeaway
When selecting an AI model for your business, look beyond flashy demos or impressive scores. The recent experiment shows that integrity under pressure is key—an AI that can read deeply, stay disciplined, and resist manipulation is worth its weight. The league is open, and with models like Kimi K3 leading the way, the era of reliable AI management is just beginning. For a deeper dive into the results and to watch the models in action, visit firmulate.com/benchmarks.html.
**Note:** K3 ran without an effort parameter (API default), while others ran at xhigh, which is important for fair comparison.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.